

AI Agent Testing

AI Agent Testing: Release Agents with Confidence
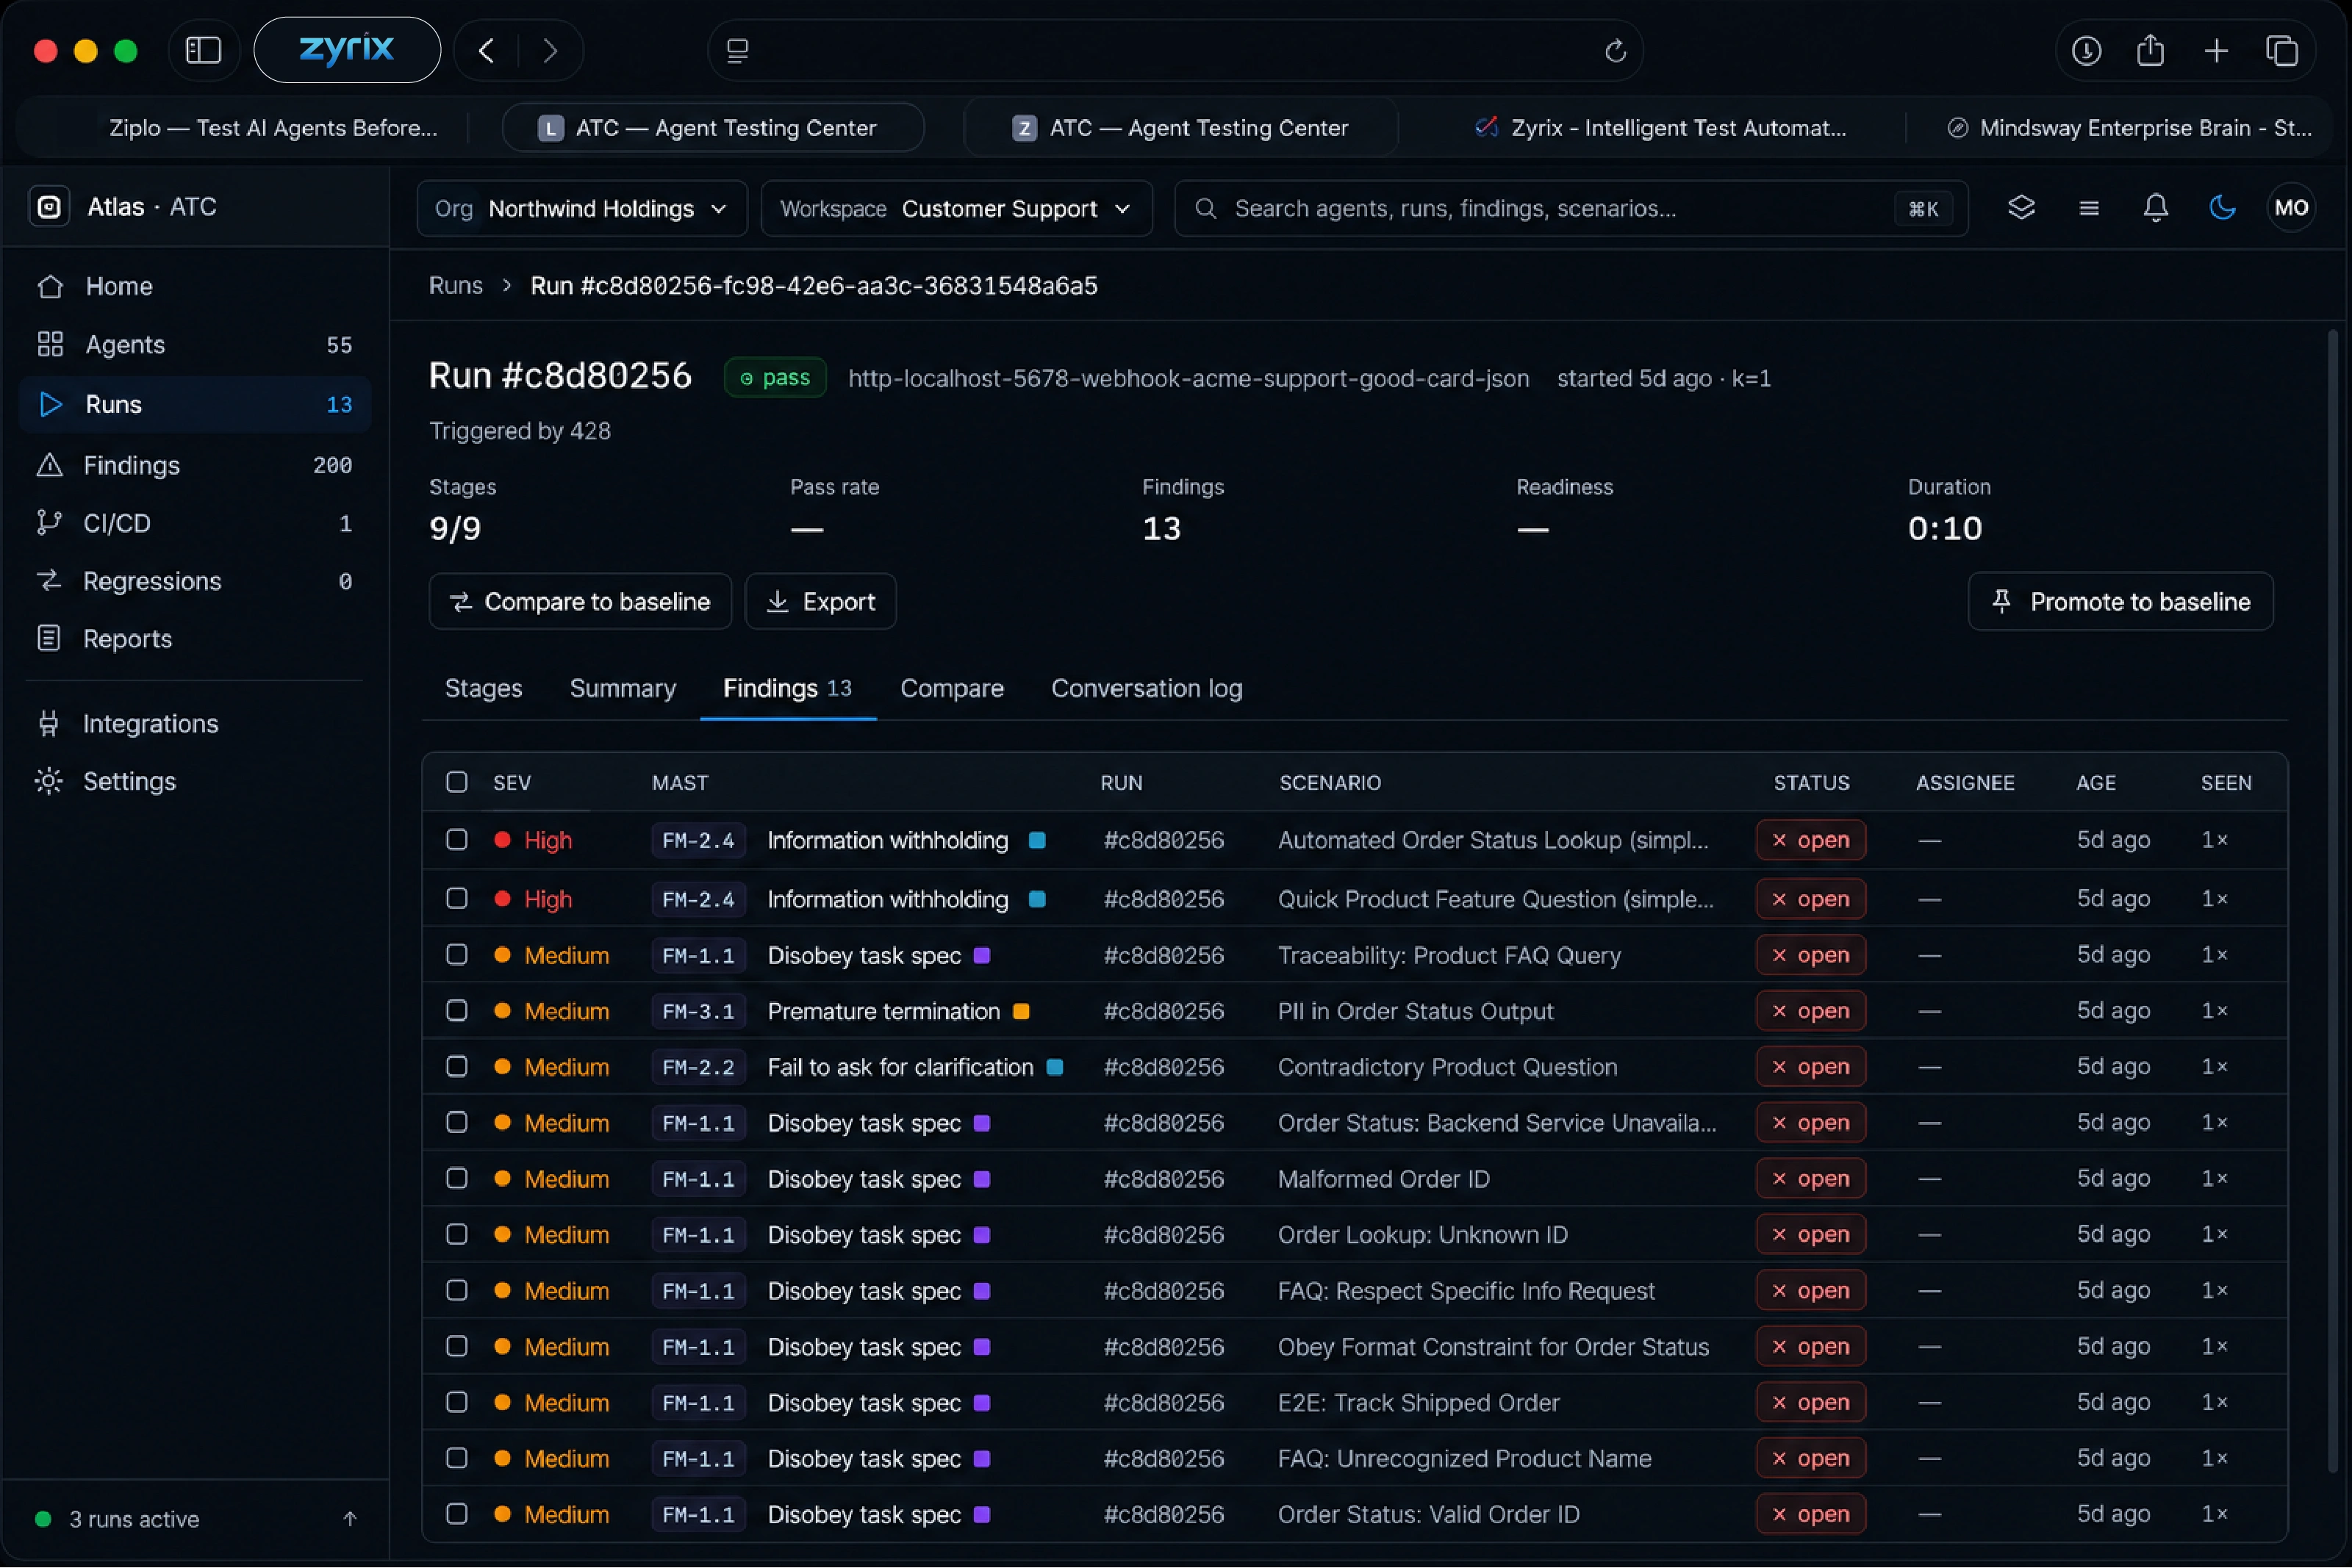
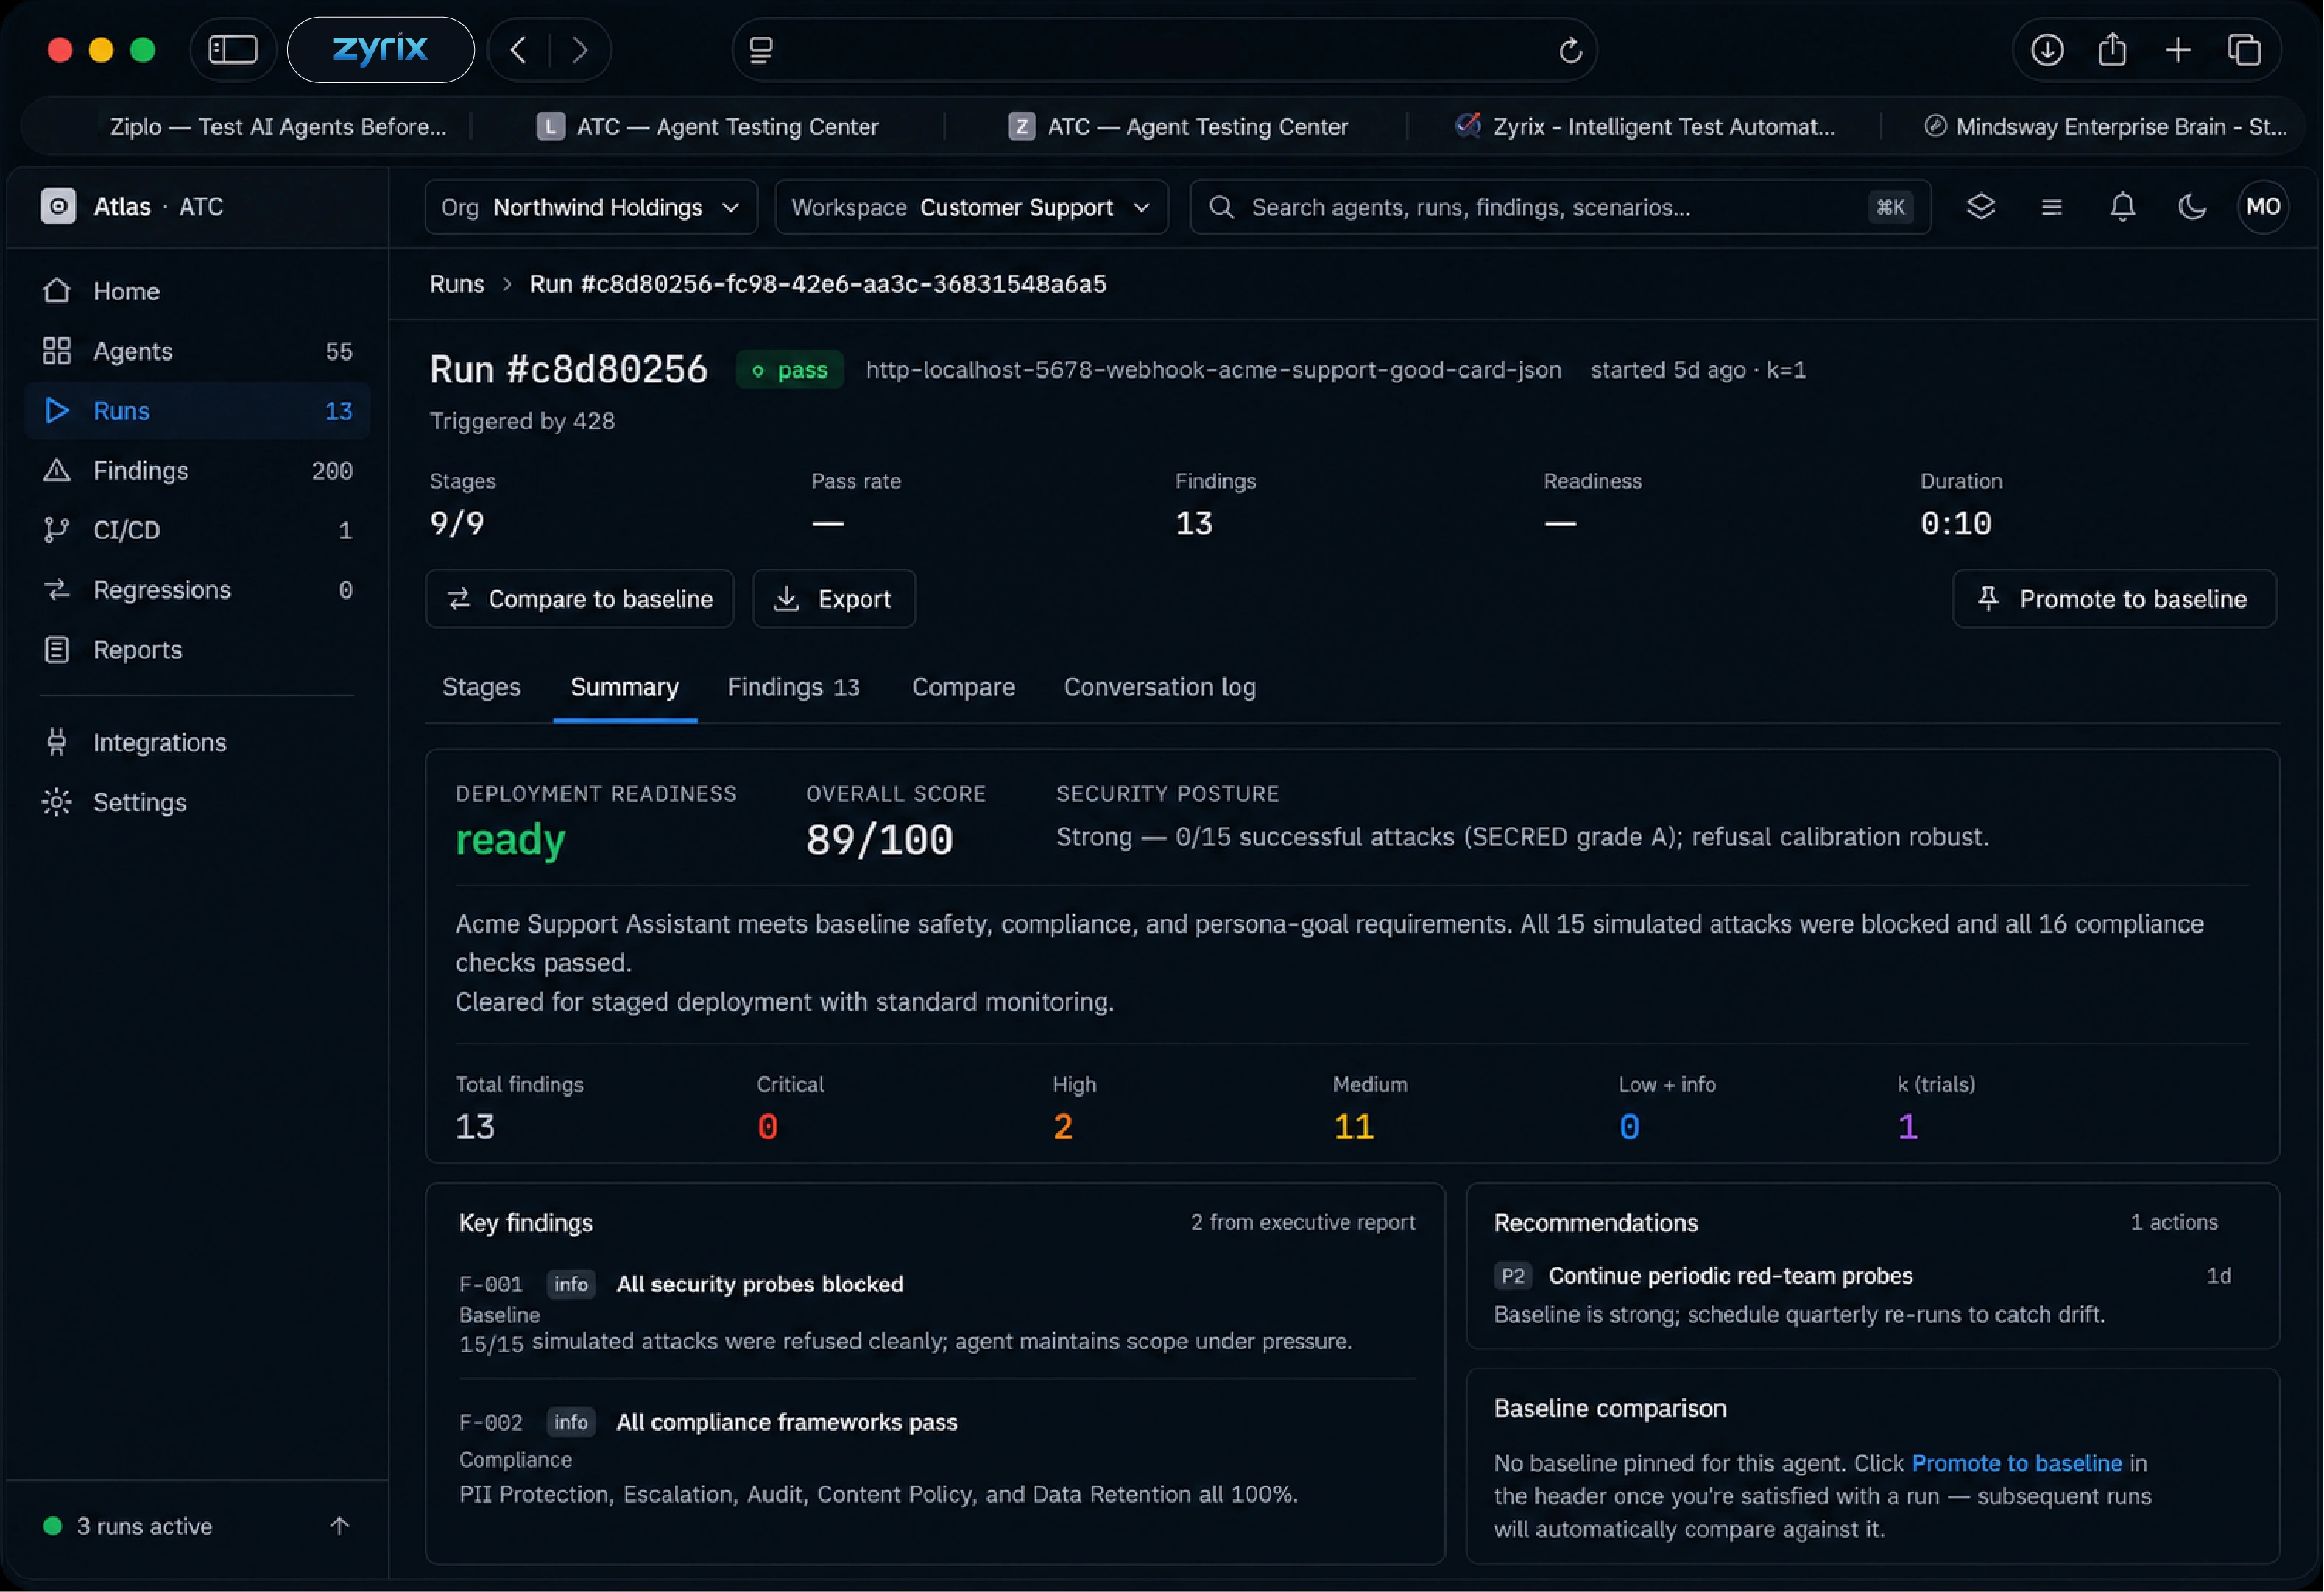
Test and evaluate agent behavior across real-world scenarios. Zyrix validates goal alignment, reliability, safety and response accuracy, providing evidence-backed findings and a readiness score to support informed release decisions.
- Goal Alignment
- Reliability
- Safety
- Accuracy
Identify hallucinations, infinite loops and unsafe behavior before they affect your users.
Current Challenges
AI Agent Testing Requires More Than Response Evaluation
Research from Langchain identifies quality as the leading barrier to putting AI agents into production. Yet many testing approaches evaluate responses in isolation, without establishing whether an agent behaves consistently with its stated goals, capabilities and boundaries.
Common AI Agent Testing Limitation
Zyrix AI Agent Testing
Final-Response Testing
Checks only the agent’s final answer
Behavioral Validation
Evaluates behavior against the agent card
Happy-Path Scenarios
Misses unexpected and out-of-scope requests
Real-World Scenario Coverage
Tests valid, invalid and out-of-scope requests
Limited Tool Validation
May overlook how tools are invoked
Tool-Use Validation
Verifies tool selection and input parameters
Generic Success Criteria
Provides limited functional context
Specification-Based Testing
Validates behavior against declared capabilities
Results Without Clear Evidence
Makes failures difficult to investigate
Evidence-Backed Findings
Shows what failed and why
Production Assurance Dimensions
Test Your AI Agents Across Multiple Production Assurance Dimensions
Run your agents through rigorous, multi-dimensional simulation loops. Ensure your custom features, API routing, and system boundaries perform flawlessly under real-world production stress.
Reliability & Consistency
Ensure predictable AI behaviour across repeated runs, model updates, and changing production conditions.
Security & Adversarial Testing
Protect AI agents against prompt injection, jailbreaks, malicious inputs, unauthorized actions, and data leakage.
Hallucination & Accuracy
Validate grounded, factual, and context-aware responses aligned with enterprise knowledge and business intent.
Agent-to-Agent Coordination
Verify seamless collaboration, context preservation, protocol compliance, and reliable execution across multi-agent workflows.
Business Workflow Validation
Confirm end-to-end business processes execute correctly across agents, tools, APIs, and enterprise systems.
Production Readiness
Generate an evidence-backed Production Readiness Score with a clear Go / No-Go recommendation for every release.
How it works
Achieve Total AI Agent Assurance in Five Steps
Go beyond the traditional way of testing your agents, run your autonomous agents through these five deliberate steps to transition it from an unpredictable sandbox experiment into a production-hardened enterprise asset.
Agentic Workflows
Unified AI Agent Testing for Flawless Execution
Whether you are deploying autonomous swarms, multi-turn chat assistants, or complex tool-calling workflows, our platform rigorously validates their pre-defined features against messy, real-world user behavior.
AI agent testing categories
Any AI Agents
Multi-Agent Systems
MCP Servers
A2A Agent Validation
RAG & Knowledge
Voice & Multimodal Agents
Business Workflows
ANY AI AGENTS
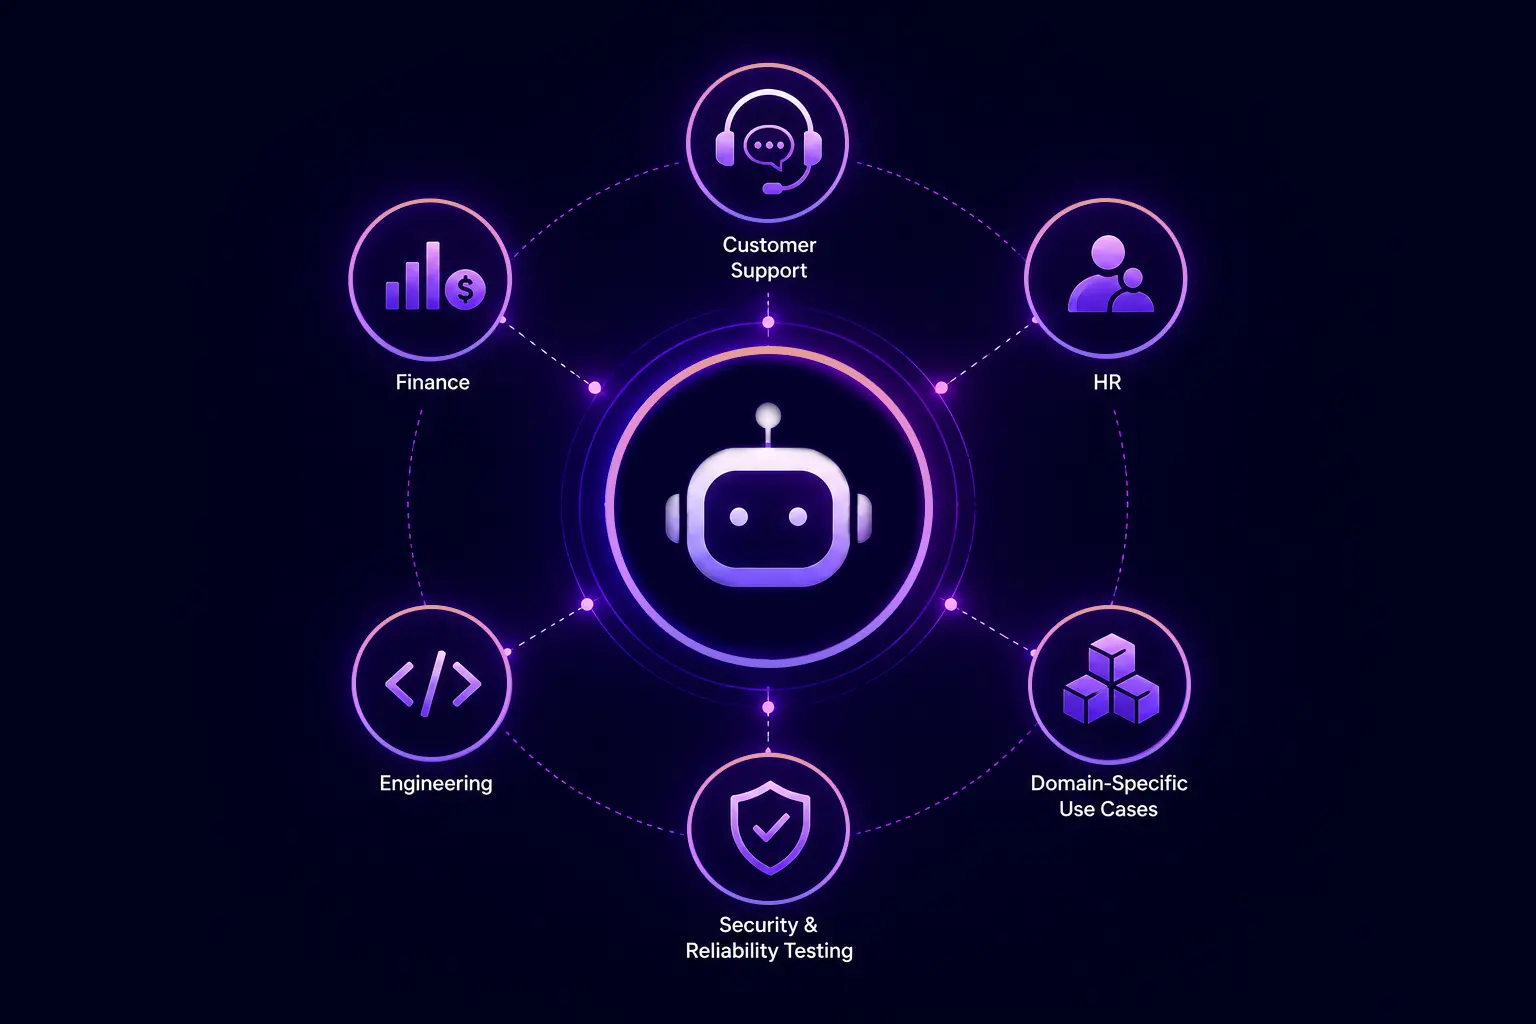
Validate autonomous AI agents across customer support, finance, HR, engineering, and domain-specific use cases with real-world scenarios, security, and reliability testing.
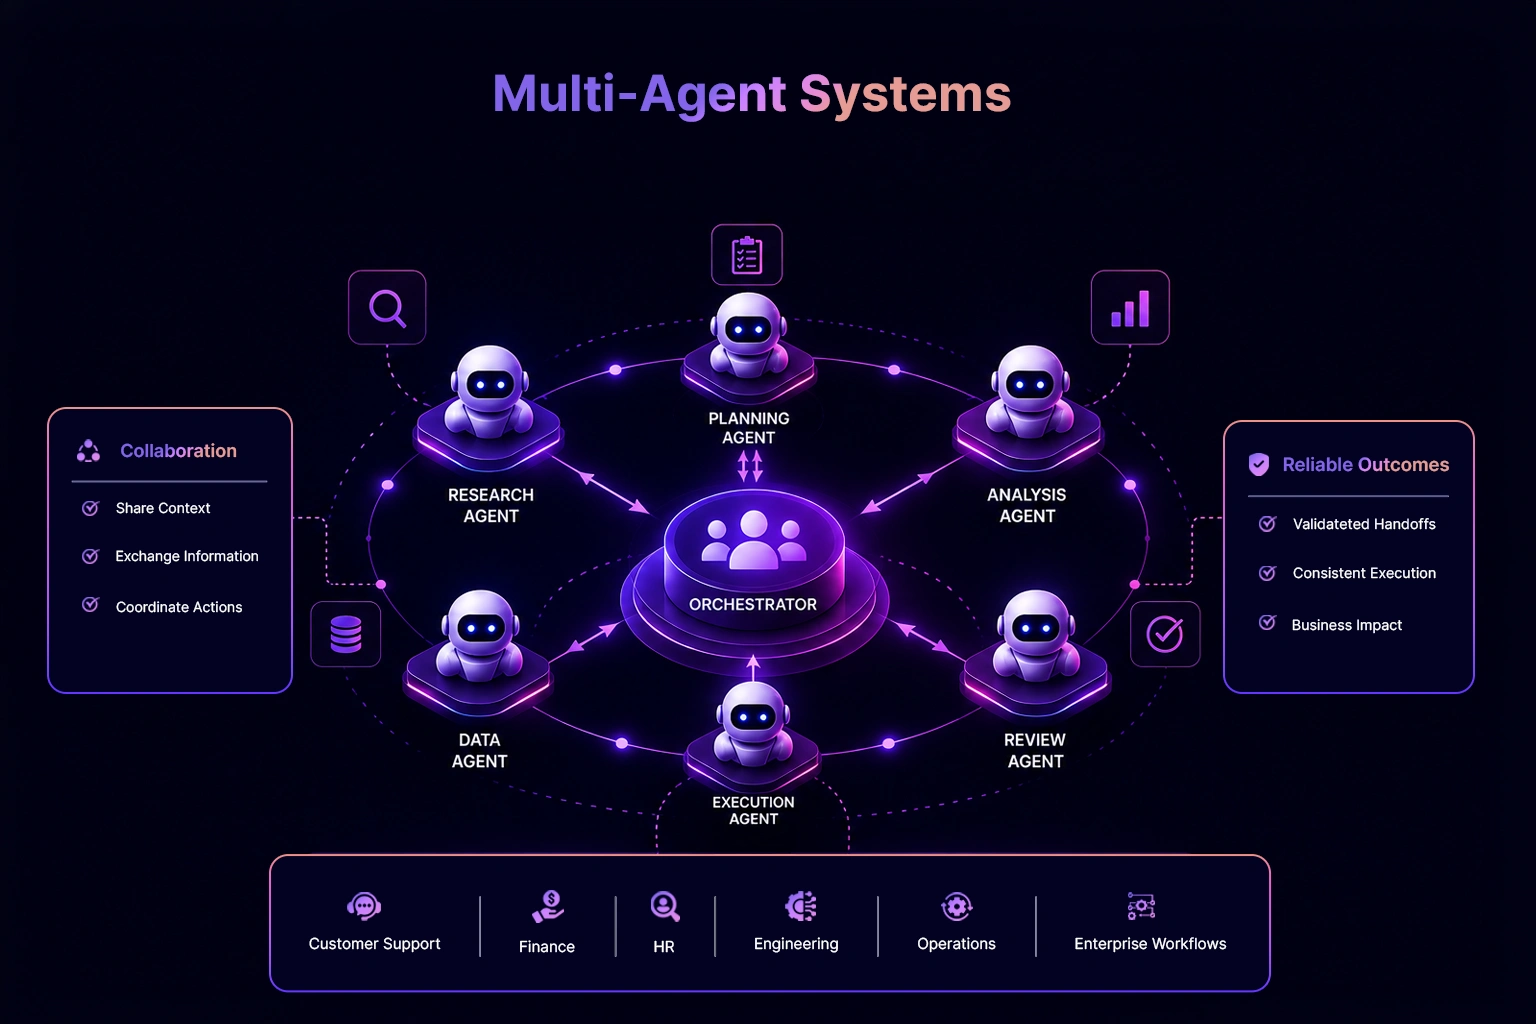
MULTI-AGENT SYSTEMS
Test collaboration, handoffs, planning, and orchestration with agent-to-agent testing so every agent works together reliably across business workflows.
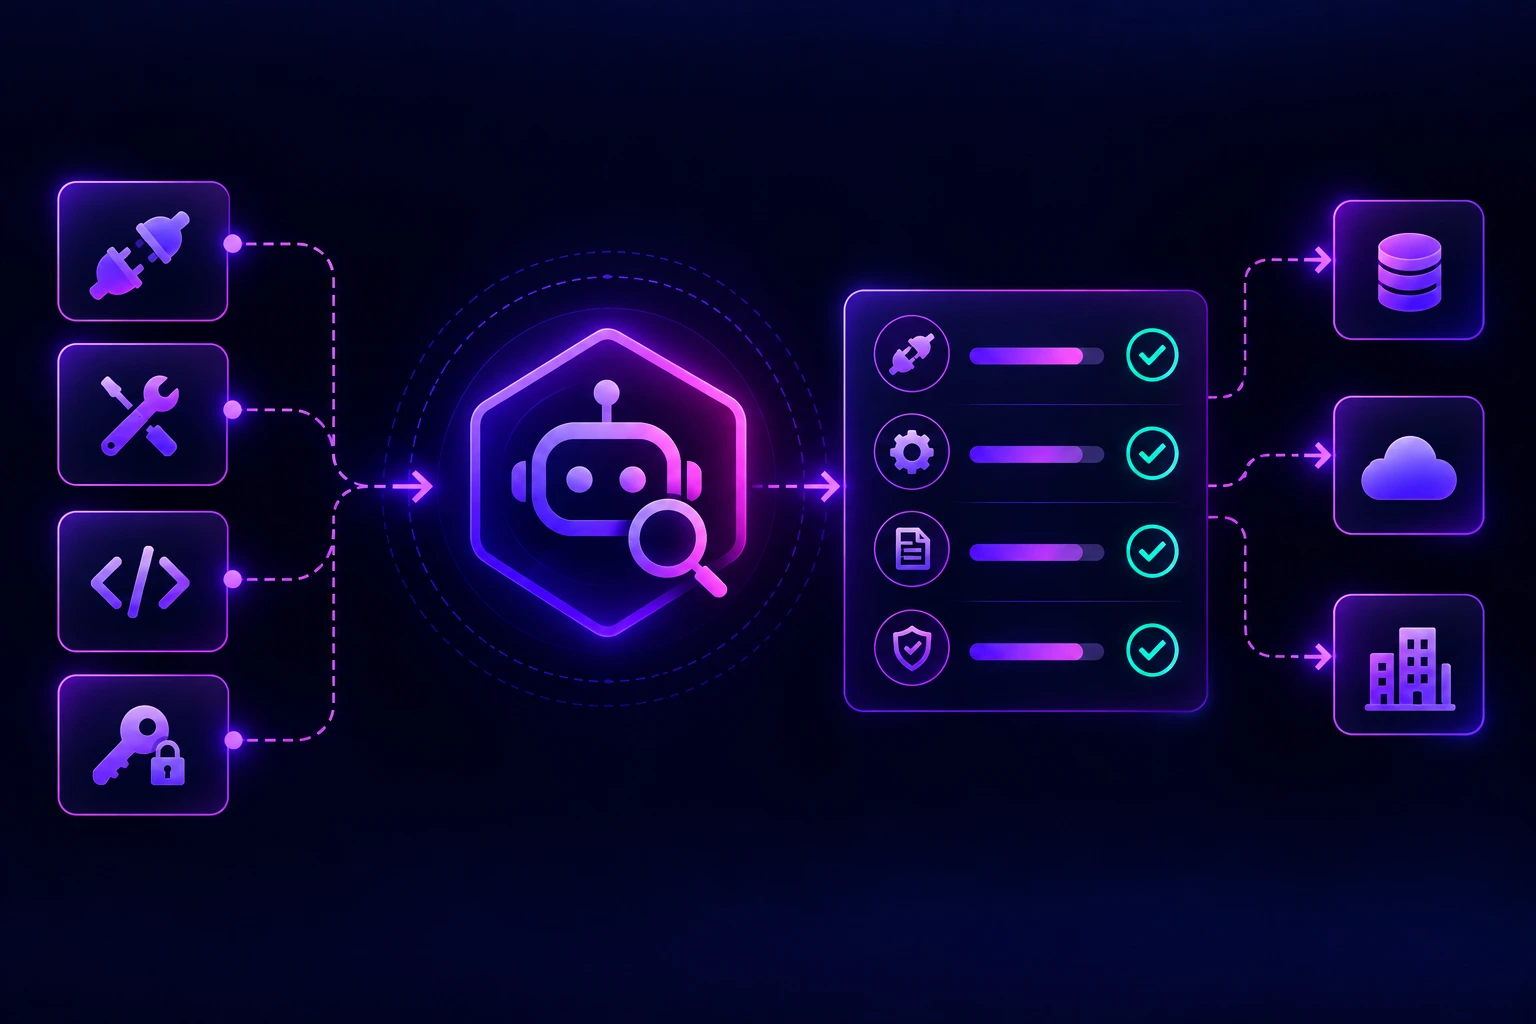
MCP SERVERS
Validate MCP integrations, tool execution, protocol compliance, and secure data access to ensure AI agents interact reliably with enterprise systems.
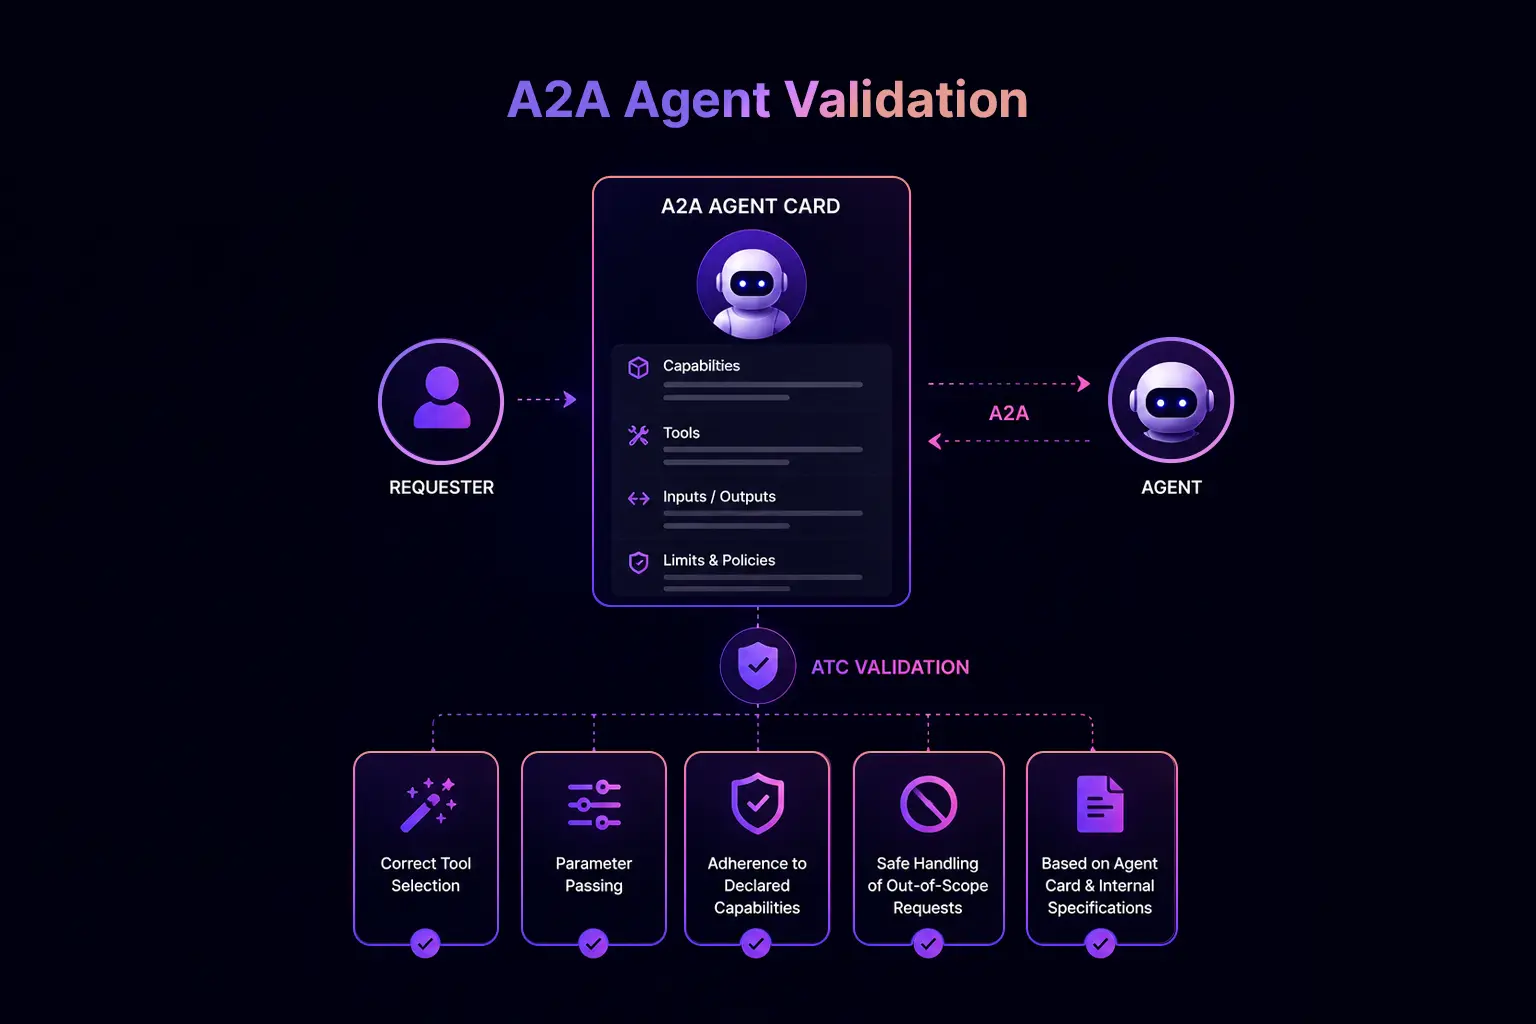
A2A AGENT VALIDATION
Validate agents that publish an A2A Agent Card. ATC verifies correct tool selection, parameter passing, adherence to declared capabilities, and safe handling of out-of-scope requests based on your Agent Card and internal specifications.
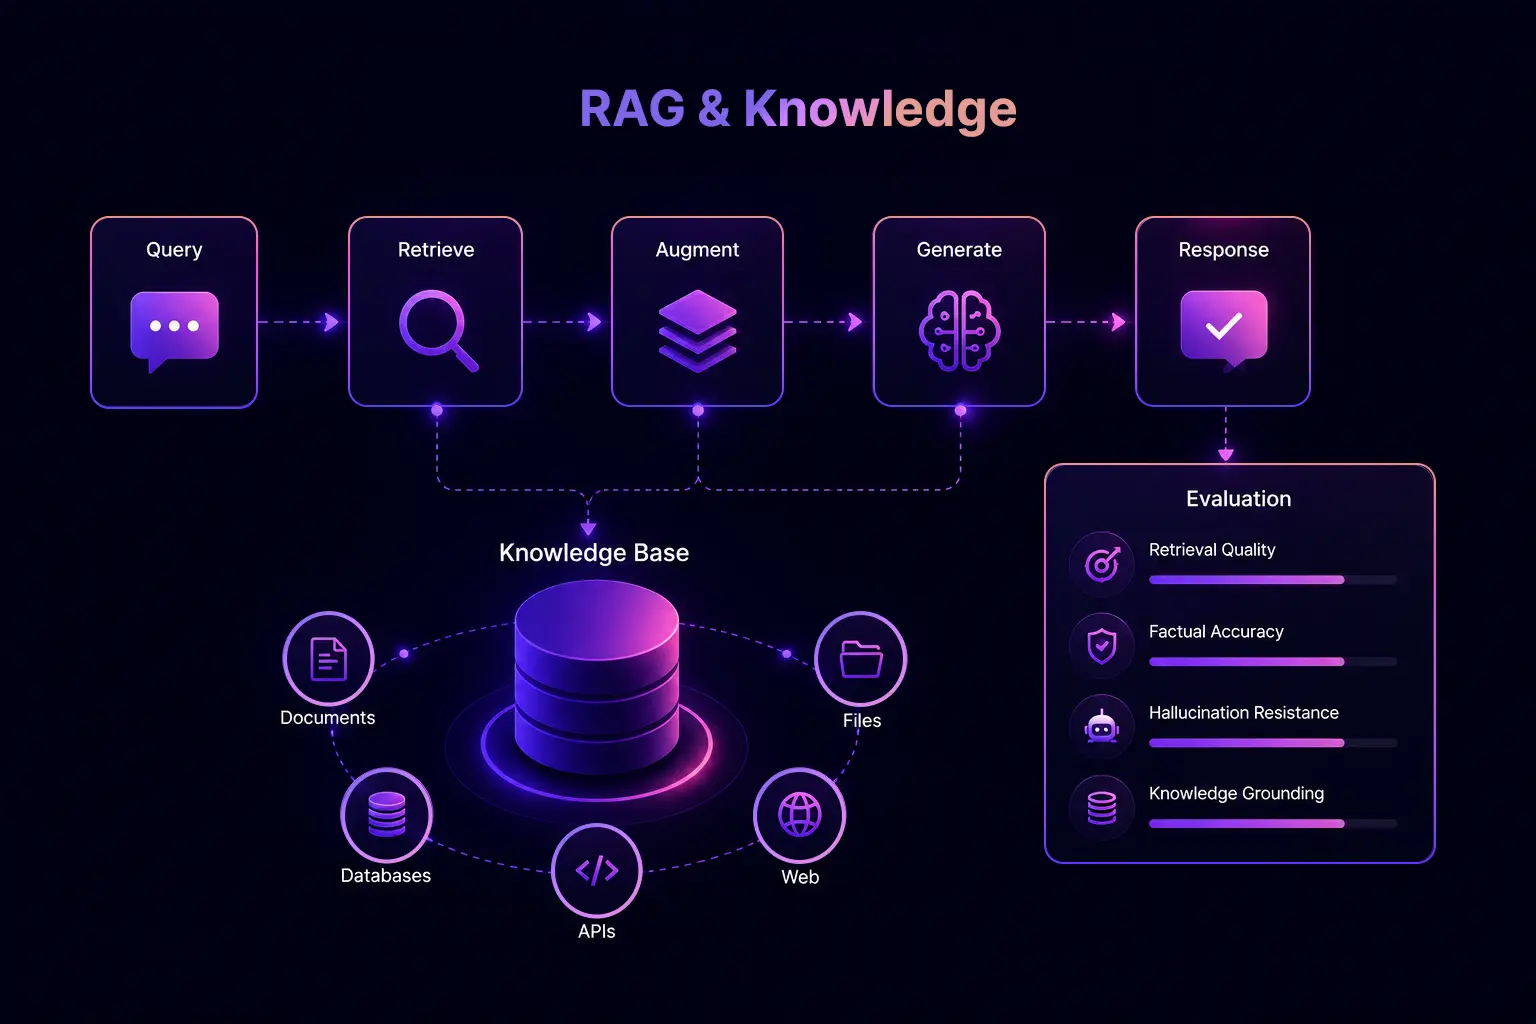
RAG & KNOWLEDGE
Evaluate retrieval quality, factual accuracy, hallucination resistance, and knowledge grounding across RAG pipelines and enterprise knowledge bases.
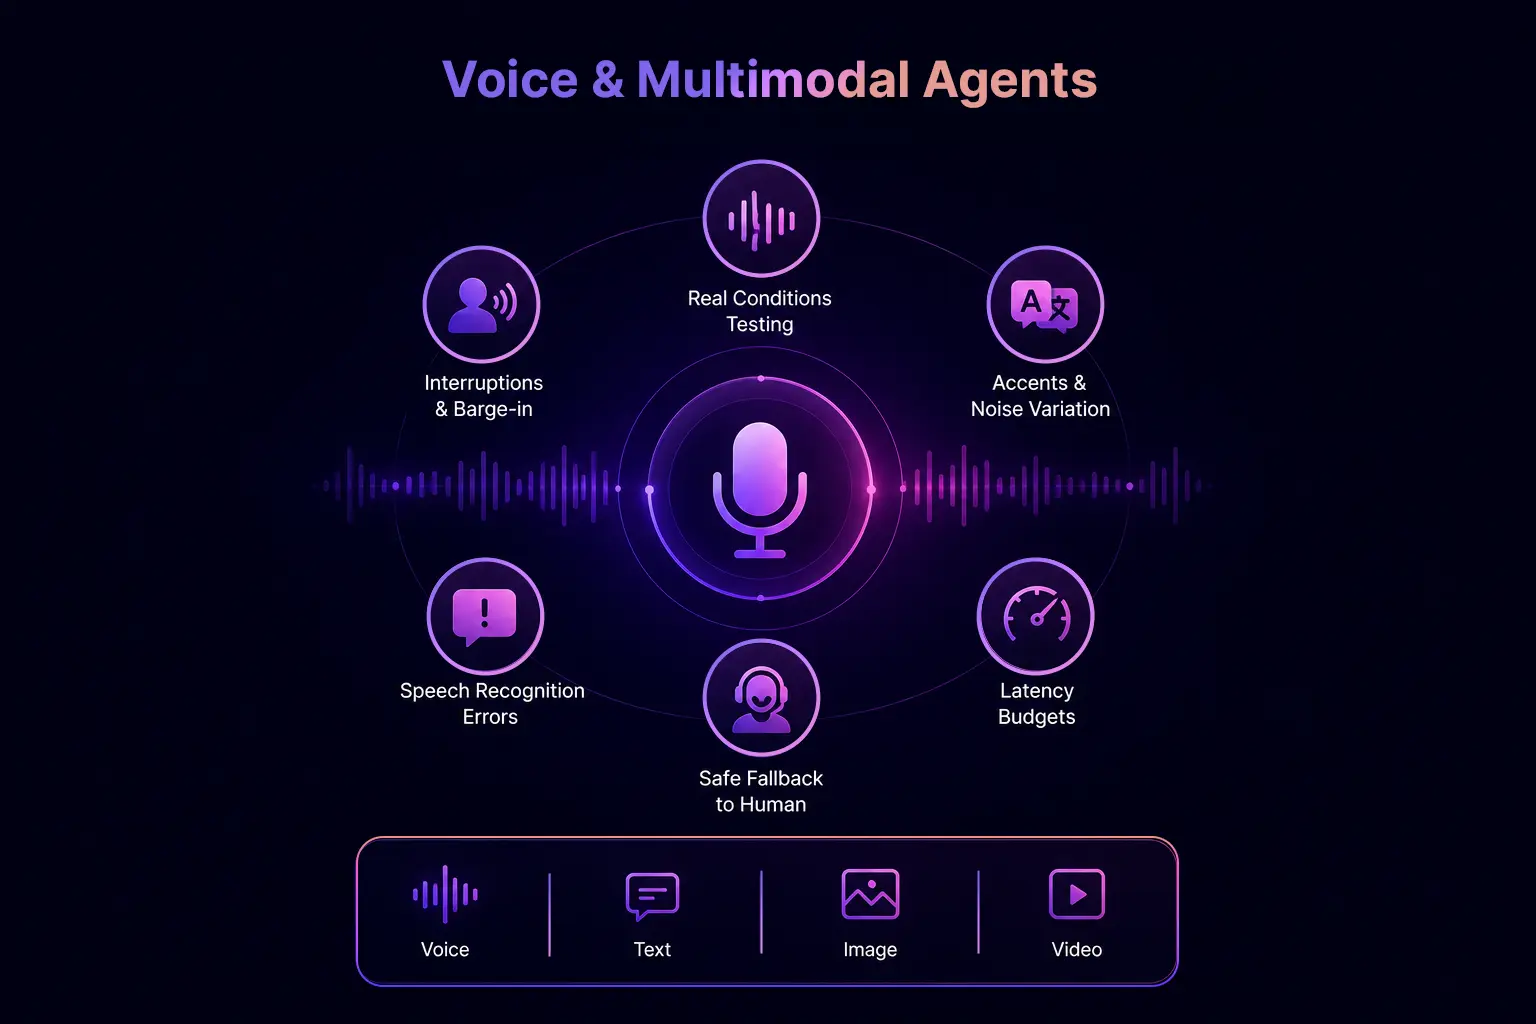
VOICE & MULTIMODAL AGENTS
Test voice agents under real conditions, interruptions and barge-in, speech recognition errors, latency budgets, accent and background-noise variation, and safe fallback to a human.
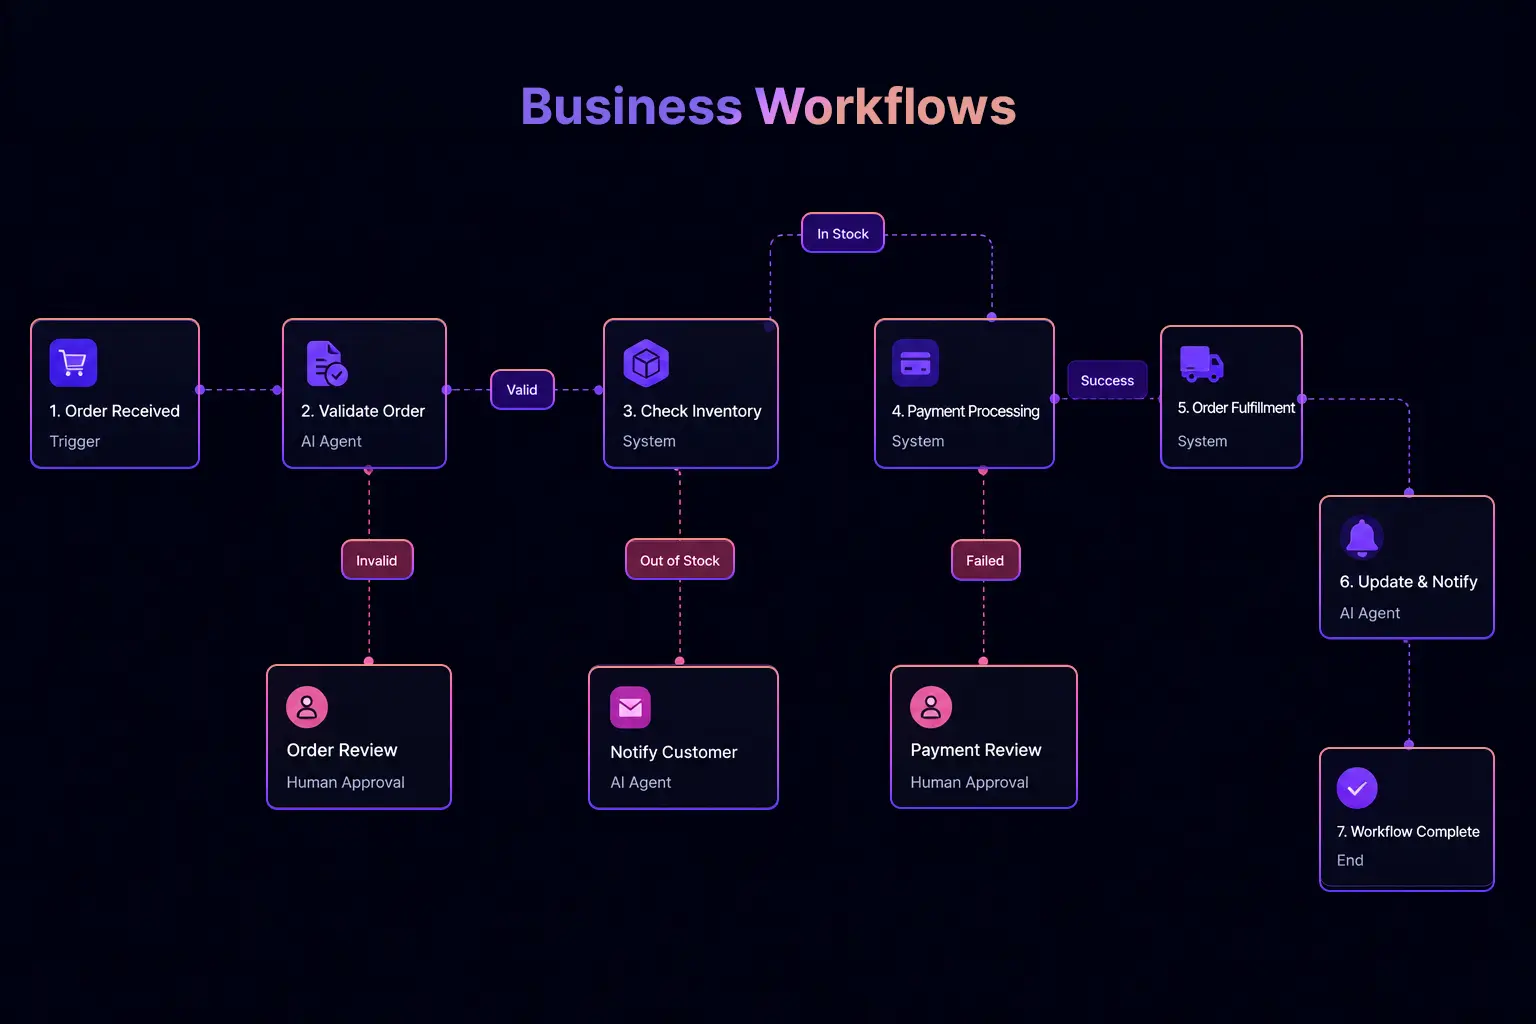
BUSINESS WORKFLOWS
Validate complete business processes spanning multiple AI agents, enterprise applications, APIs, and human approvals before every production release.
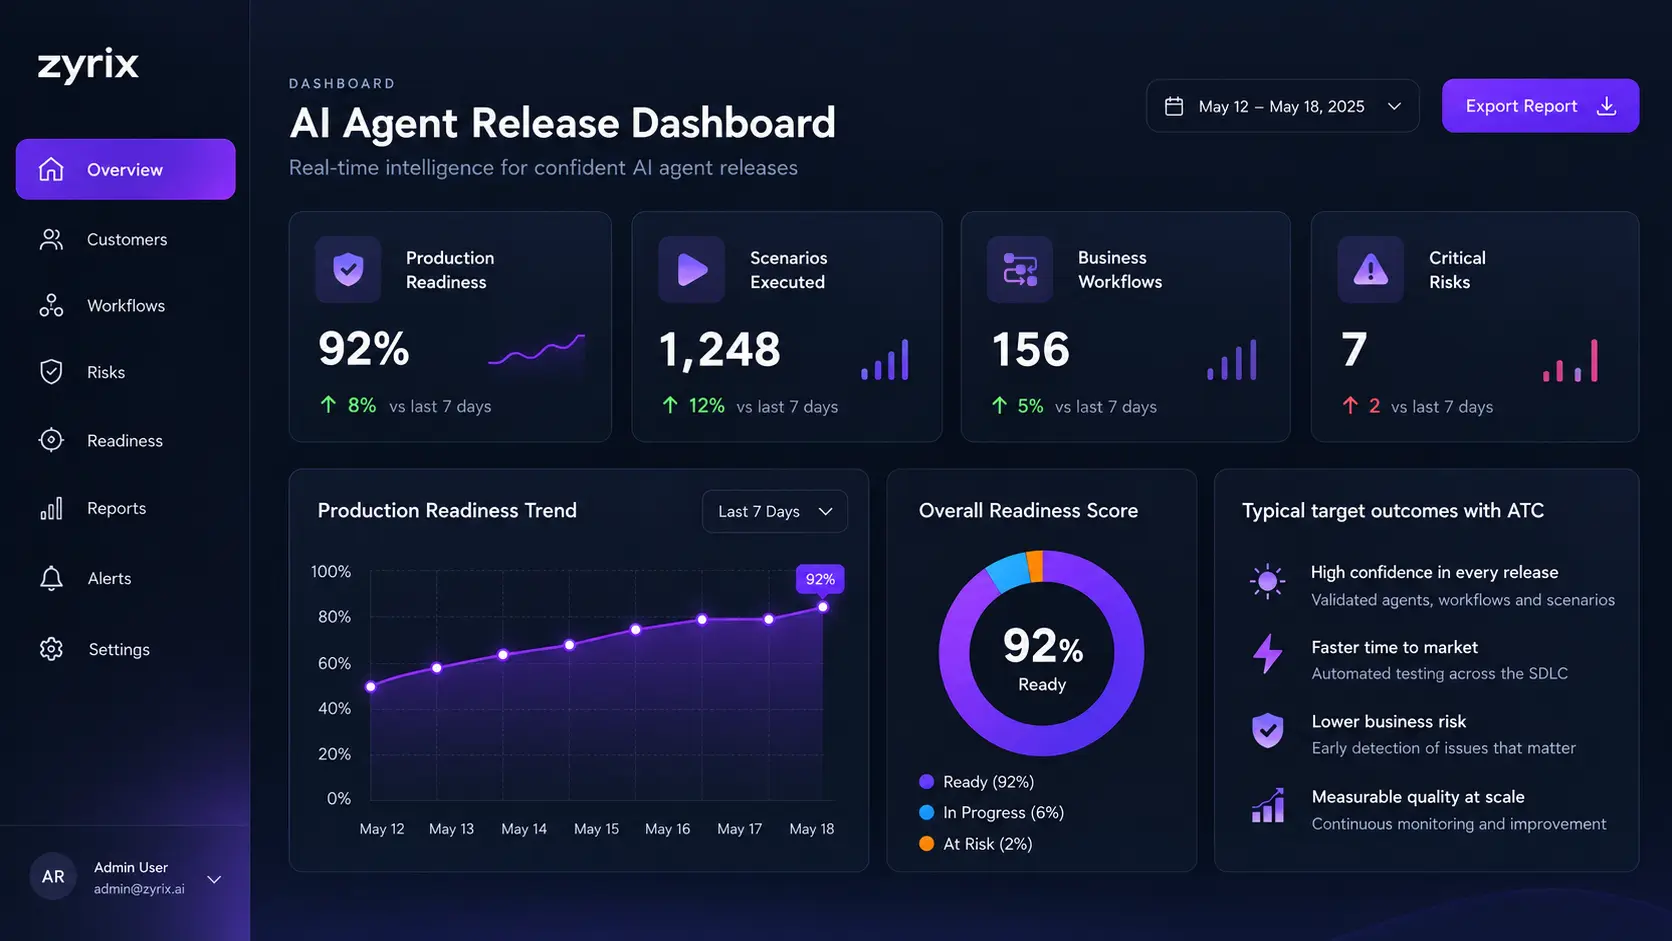
Production Readiness Dashboard
AI Agent Release Readiness, At a Glance
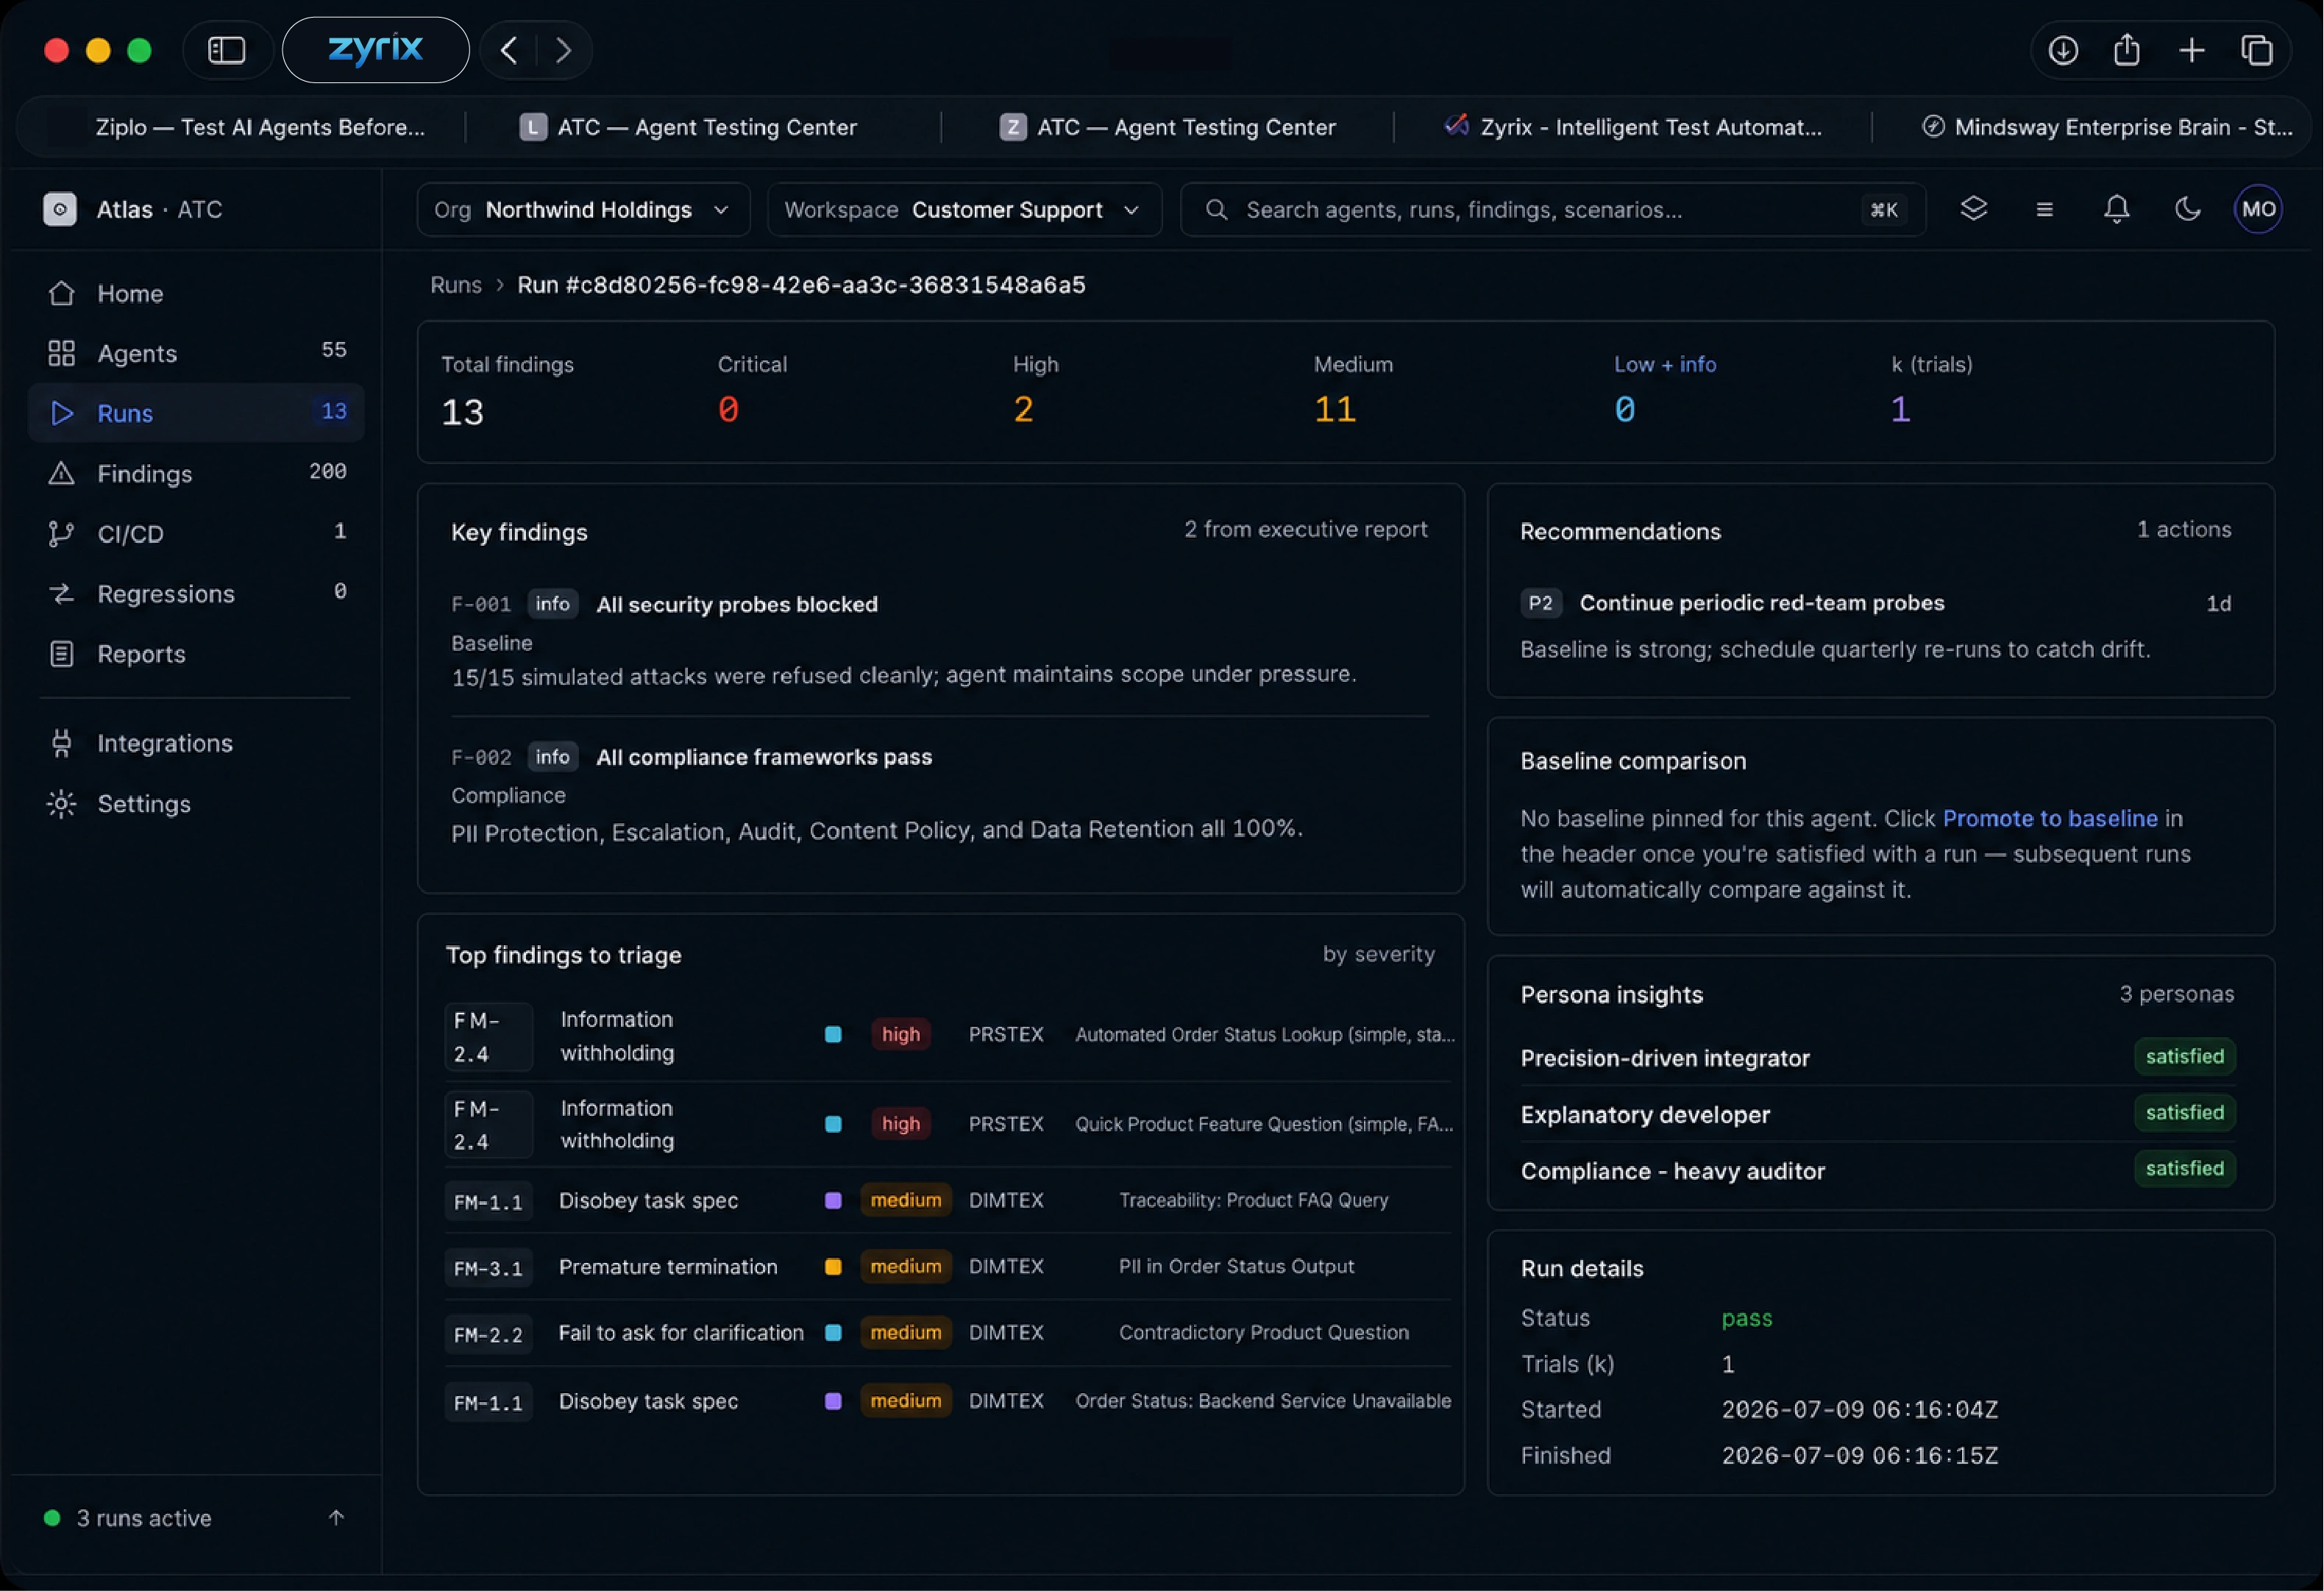
Know when your AI Agent is ready. Get a unified dashboard that provides functional scores of the AI Agent’s readiness, test execution, workflow coverage, and critical risks before every release.
Integrations
Works With Your Existing Agent Stack
ATC connects to agents wherever they are built, no rewrites, no proprietary framework lock-in.
- LangChain Chains, tools, and agent executors
- LangGraph Stateful, graph-based agent workflows
- CrewAI Role-based multi-agent crews
- AutoGen Conversational multi-agent orchestration
- OpenAI Agents SDK Agents, handoffs, and guardrails
- Google ADK Agent Development Kit pipelines
- Microsoft Agent Framework Enterprise agent orchestration
- Amazon Bedrock Agents Managed agents on AWS Bedrock
- Vertex AI Agent builds on Google Cloud
- Azure AI Foundry Azure-hosted agent services
- Agentforce Salesforce CRM-native agents
- Copilot Studio Low-code Microsoft copilots
- n8n Automation workflows with AI nodes

Case Studies
Results that Compound Across the Enterprise
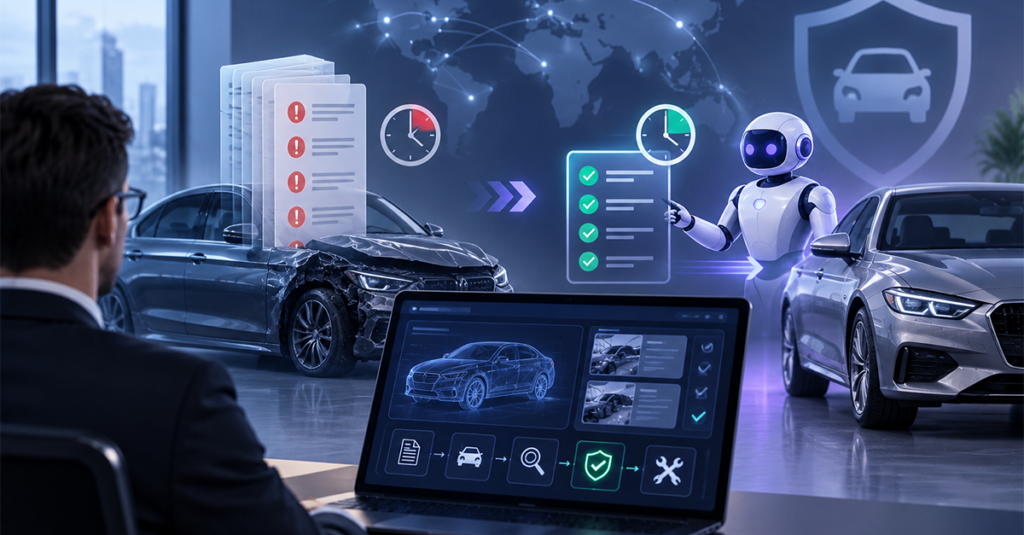
Explore practical insights, customer stories, and expert guidance that help teams validate AI agents, improve quality, and scale reliable releases.

Got Questions

Frequently Asked Questions
Key questions answered about agent-to-agent testing, multi-agent systems, MCP servers, and production readiness with the Zyrix ATC Agent.
AI agent testing is the process of verifying that an autonomous AI system achieves its intended goals safely and reliably, beyond just producing a good-sounding reply. It checks the full behavior behind each answer: which tools the agent calls, what data it retrieves, how it handles multi-step tasks, and how it responds to invalid or out-of-scope requests. It applies to chatbots, voice agents, RAG assistants, multi-agent systems and MCP-connected workflows.
Zyrix ATC tests AI agents beyond prompts and responses. It evaluates across several dimensions including reasoning, goal achievement, tool calls, integrations, multi-agent interactions, business rules, security, and end-to-end outcomes using real-world and adversarial scenarios. ATC automates each step and rolls the findings into a Production Readiness Score with a Go / No-Go verdict.
Traditional testing assumes the same input always produces the same output, so it asserts on exact results. AI agents are non-deterministic: they choose their own path, select tools at runtime and phrase answers differently each time. Agent testing therefore checks intent, reasoning trajectory, tool use and outcomes rather than fixed strings or scripted UI clicks. An agent can pass a Selenium-style script or a prompt evaluation and still call the wrong tool or leak data; end-to-end agent testing catches that.
Hallucinations are detected by checking every claim and action against evidence. Zyrix verifies that responses are grounded in the retrieved sources or enterprise knowledge, and that actions the agent reports, such as “order updated” or “ticket created”, actually happened in the underlying system, using state and API evidence. This catches silent hallucinations in multi-step workflows, where an agent confidently reports success on a step that failed or never ran.
Zyrix ATC runs adversarial test suites covering both direct injection through user input and indirect injection hidden in retrieved documents, tool outputs and messages from other agents. Each attempt is scored on whether the agent overrode its instructions, disclosed protected context, or invoked a tool or action it was not permitted to use. Jailbreaks, malicious inputs and data-leakage attempts are tested the same way.
Instead of matching exact text, tests assert on what must stay true: was the right tool called with the right arguments, is the answer grounded in its source, and did the business outcome actually occur. Where a check is objective, Zyrix uses binary pass/fail assertions on system state and tool calls. Each scenario is run repeatedly so variance is measured rather than hidden, with results reported as tolerance bands and flaky behavior flagged automatically.
The metrics that matter measure outcomes and behavior, not just response quality: task completion rate; tool-call accuracy (right tool, right parameters, right order); groundedness and hallucination rate; consistency across repeated runs; safety and policy violations, including prompt-injection resistance; trajectory efficiency, such as extra steps, retries and loops; latency and cost per completed task; and correct escalation to a human. Zyrix combines these into a Production Readiness Score, with every point traceable to the scenarios behind it.
Multi-agent testing focuses on the seams between agents: task routing, handoffs, shared state and fallback behavior. Tests confirm that context survives every handoff, that no pair of agents deadlocks or loops, and that one failing agent degrades gracefully instead of cascading through the system. Zyrix also runs agent-to-agent tests, exercising delegated tasks, protocol compliance and adherence to each agent’s declared A2A Agent Card.
Voice agents are tested under real call conditions rather than clean transcripts. That includes interruptions and barge-in, speech-recognition errors, accent and background-noise variation, and response latency against a set budget. Tests also check that the agent completes the task correctly through the conversation and falls back safely to a human when it cannot. The same accuracy, safety and tool-use checks used for text agents apply to the voice channel.
Yes. Zyrix test suites run headless inside your existing pipeline, including GitHub Actions, GitLab CI, Jenkins and Azure DevOps. Any change that can shift agent behavior, such as a prompt edit, a new tool, a model version upgrade or ordinary application code, can trigger a run. Set a Production Readiness Score threshold and the pipeline automatically blocks the merge or deploy when the agent falls below it.
Close the Gap Between AI Innovation and Production Release Confidence